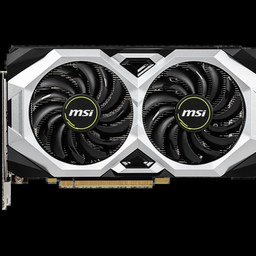
| 1 | | 370 | 575W | $2,2802 used · from $2,195 |
| 2 | | 272.8 | 250W | — |
| 3 | | 264 | 1000W | — |
| 4 | | 238 | 600W | — |
| 5 | 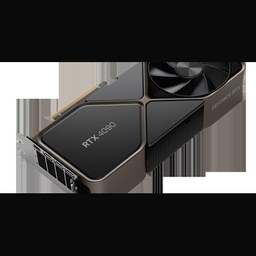  RTX 409024 GB VRAMSwift 1.5 Qwen3.8 Flash-Next | 220 | 450W | $1,2851 used · from $1,290 |
| 6 | | 177.6 | 230W | — |
| 7 | | 158.3 | 700W | — |
| 8 | | 127 | 240W | $8,0501 used · from $7,990 |
| 9 | | 127 | 370W | — |
| 10 |   M5 Max64–128 GB unifiedQwen3.8-Flash-Next | 126.5 | 70W | $3,3201 used · from $3,280 |
| 11 | | 120 | 600W | — |
| 12 | | 108.6 | 45W | — |
| 13 | | 100.6 | 350W | — |
| 14 | | 99.9 | 360W | — |
| 15 | RTX PRO 600096 GB class, 81–85 GB used in the quoteQwen3.8-Flash-Next | 92.8 | 600W | — |
| 16 | | 89.9 | 40W | — |
| 17 | | 88 | 160W | — |
| 18 |  M4 Pro24–64 GB unifiedQwen3.6-35B-A3B | 85.5 | 45W | $1,9101 used · from $1,890 |
| 19 | | 81.5 | 1400W | — |
| 20 | | 79 | 350W | — |
| 21 | | 66.7 | 250W | — |
| 22 | | 61.9 | 27W | — |
| 23 | | 60 | 1000W | — |
| 24 | | 57 | 250W | — |
| 25 |  RTX 4060 Ti8–16 GB VRAM, size not in the quoteQwen3.8-Flash-Next | 55 | 165W | — |
| 26 | | 54.7 | 180W | $3851 used · from $390 |
| 27 | | 53.8 | 140W | — |
| 28 | | 53.5 | 300W | — |
| 29 | | 52.7 | 320W | — |
| 30 | | 52 | 600W | — |
| 31 |  RTX 30608–12 GB VRAMEmpero Qwen3.8-35B-A3B | 50 | 170W | $1621 used · from $165 |
| 32 | | 50 | 360W | — |
| 33 | RTX 50608 GB VRAMMiMo-V2.6-Distill-Qwen-9B | 47 | 145W | — |
| 34 | | 40 | 125W | $781 used · from $75 |
| 35 | | 40 | 340W | — |
| 36 | | 37 | 60W | — |
| 37 | | 34.2 | 500W | — |
| 38 | | 32.4 | 150W | — |
| 39 | | 26.8 | 300W | — |
| 40 | | 11.3 | 70W | — |
| 41 | | 10 | 304W | — |
| 42 | | — | 500W | — |
| 43 | | — | 60W | — |
| 44 | | — | 27W | — |
| 45 | | — | 140W | — |